
Quick answer: speaker identification answers the question of who is speaking. It compares a voice sample against a set of enrolled voiceprints and returns the closest match, a 1:N search. It differs from speaker verification, which is a 1:1 check of a claimed identity.
Speaker Identification, a subset of speaker recognition, is the technology that determines the identity of an unknown speaker by comparing their voice characteristics with the voice characteristics of known speakers. Thus, it’s also known as Speaker Search or Speaker Spotting. This article explains what Speaker Identification, how it identifies speakers, and how it differs from Speaker Verification.
What does Speaker Identification do?
Speaker Identification matches a voice sample of an unknown user with voice IDs of known users. Imagine a business meeting with tens of participants. A Speaker Recognition engine can identify speakers as they speak. It offers convenience as it spots speakers even if they don’t use separate devices or log in with employee credentials. It enables a wide range of applications across industries, such as
- Healthcare: Telehealth applications identify patients with chronic conditions and store their information in their medical records using
Speaker Identificationas they report their status. - Law Enforcement:
Speaker Identificationenables law enforcement agencies to identify suspects by comparing voice recordings from crime scenes vs. known voice samples. - Customer Service: Agents or IVRs provide personalized experiences and tailor their interactions to individuals by identifying a customer's voice.
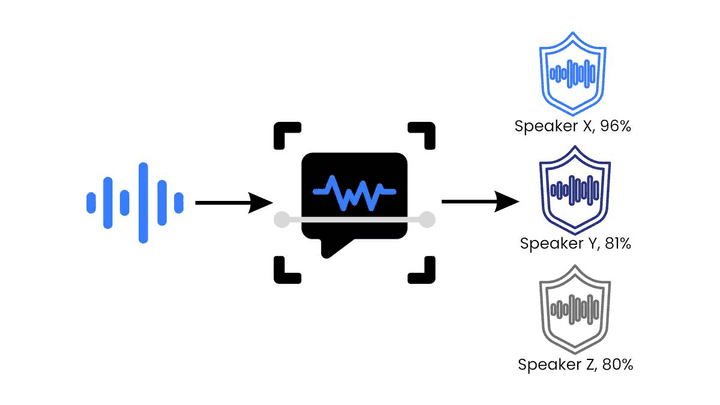
How does Speaker Identification work?
Speaker Recognition engines create voice IDs (enrollment) and compare them with existing voice IDs (matching). An engine
- analyzes the new voice sample
- predicts the likelihood of a match between the sample and voice IDs,
- returns scores that show the likelihood of the match or just a list of potential matches
Speaker Identification vs. Speaker Verification
Speaker Identification and Speaker Verification are both subsets of Speaker Recognition. If a speaker claims an identity, Speaker Recognition engines use the voice sample to confirm (verify) the claimed identity. Hence, it’s called Speaker Verification. If a speaker doesn’t claim an identity, Speaker Recognition engines use the voice sample to find (identify) the match within multiple (possibly many) voice IDs. Hence, it’s called Speaker Identification.
In a nutshell, a Speaker Recognition engine does a one-to-one match for Speaker Verification and a one-to-many match for Speaker Identification. Speaker Identification can return a list of alternatives with various probabilities, while Speaker Verification does not.
Picovoice’s Speaker Recognition, Eagle, comes with high accuracy and cross-platform support. Anyone can start building with Eagle Speaker Recognition for free and start identifying speakers in minutes.
Start Building


